Sep 30, 2026
Fake Googlebot: how to spot an impersonator
Any client can send a Googlebot user agent. Verify the IP with reverse and forward DNS or Google's published ranges, and avoid the Google Cloud trap.
Frederick Jahn
We use analytics and marketing tools to understand visits and improve this site. Read our data privacy policy.
Who operates each crawler, how to verify a request that claims to be one, and how to turn an access decision into a policy your site enforces.
Sep 30, 2026
Any client can send a Googlebot user agent. Verify the IP with reverse and forward DNS or Google's published ranges, and avoid the Google Cloud trap.
Sep 30, 2026
Pay per crawl charges AI crawlers per request. How Cloudflare, TollBit, RSL and x402 work, and why it depends on knowing which crawler is asking.
Sep 22, 2026
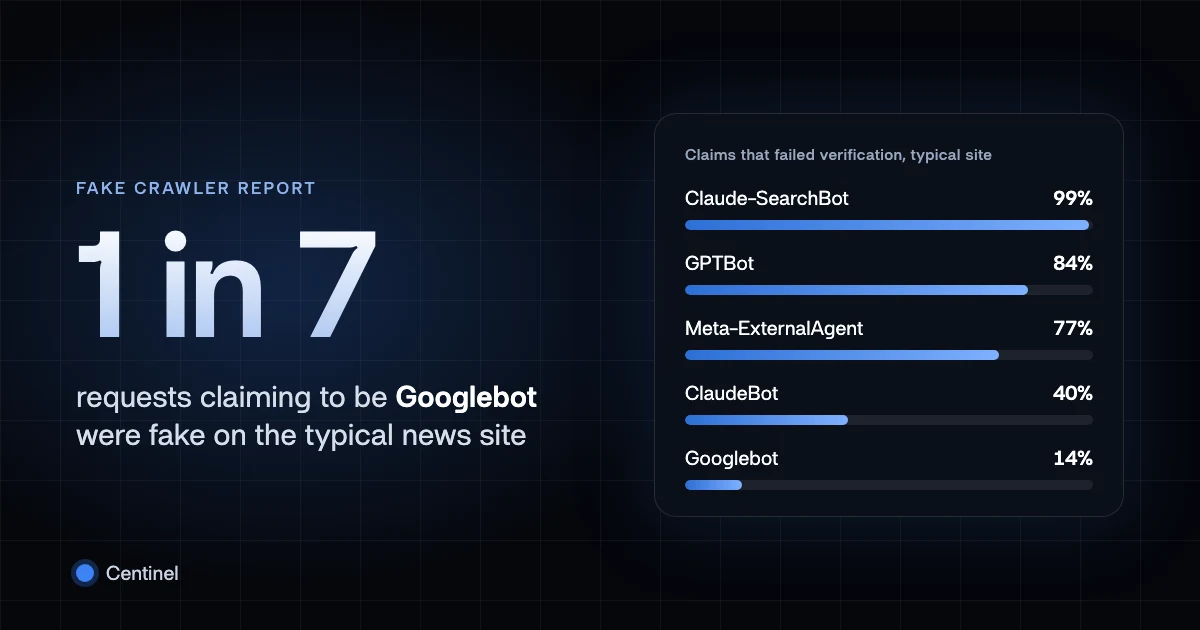
On the typical news site, 1 in 7 requests claiming to be Googlebot failed verification, and 84% of GPTBot claims were fake. Data, method and CSV download.
Sep 5, 2026
Build a crawler inventory from request logs. Separate claimed names, verified operators, resource use, and policy outcomes before changing crawler access.
Apr 20, 2026
Build a practical access policy for AI crawlers and agents with a resource matrix, explicit identity states, bounded responses, and tested failure behavior.
Apr 20, 2026
Check whether a request claiming to be GPTBot, ClaudeBot or another AI agent is real, using published IP ranges, reverse DNS or signed requests.
Apr 20, 2026
Agentic traffic comes from software that picks and performs steps toward a user's goal. How it differs from crawlers and fetchers, and how to measure it.

Mar 18, 2026
Compare GPTBot, ClaudeBot and Bytespider: what each operator says the crawler is for, its robots.txt guidance, published IP ranges, and how to check a claim.
Mar 14, 2026
Copy-ready robots.txt rules for GPTBot, ClaudeBot, Google-Extended and other AI crawler tokens, how to test them, and why robots.txt cannot stop fakes.
Mar 12, 2026
Block GPTBot, ClaudeBot and other AI crawlers: robots.txt rules by purpose, a verified request rule for copied names, and two curl checks to test the block.

Mar 10, 2026
AI crawlers collect web content for model development, AI search and retrieval. How they work, the main operators' crawlers, and what your access logs can show.
